By Kate Marquis, John Jay College
As artificial intelligence (AI) tools and AI-generated materials start to become more and more common in the field of trial consulting, practitioners may find it useful to gain a better understanding of their potential uses. In order to illustrate the utility of these tools, one may note the benefits and consequences of AI usage and then detail applications that may prove useful in the field. The subject of this article will chiefly be one specific type of use: the generation of stimulus materials to be used in mock trial research.
There are a variety of reasons why AI usage is advantageous for jury consulting, and indeed many firms have already sought new methods to utilize the technology. The most notable benefit of AI integration is the relatively low cost, both in terms of time and finances. Generative tasks– like the creation of visuals and drafting of voir dire and questionnaire items– can be ‘shortcut’ through initial drafts created by sophisticated AI. Similarly, some mock trial research materials can be quickly adapted through the use of AI.
However, though AI usage has potential benefits, there are some notable concerns to weigh. One of the most obvious concerns lies in AI’s risk to confidentiality. Not everyone has access to internal company AI servers, nor is everyone very aware of how long information stays in the cloud (Allen & Hallene, 2026). As a result, it is not uncommon for practitioners to be lulled into a false sense of security and believe that simply removing names of involved parties is sufficient to avoid accidental disclosure. Next is the risk of falsified research documents. It has been quite commonplace for court personnel to use AI as a means to summarize court materials and compile background research for cases (Jaitley et al., 2026). But even outside court settings, there have been numerous instances of AI databases citing research articles that either did not corroborate the claims that the AI indicated in their summary or simply fabricated the entire source (Ellis & Breitenstein, 2026). This can have serious repercussions for trial consultants and legal personnel who may rely on the accuracy of this information to generate an effective trial strategy or develop ideal juror profiles. The AI databases do not make these mistakes due to some kind of malicious code- it is simply how they are built. Most publicly accessible AI tools are aimed at getting you an answer even if it is incorrect, because the response ‘I don’t know’ is not desirable for the consumer. Therefore, it is the duty of the trial consultant or legal practitioner to make sure that their own knowledge base is sufficient to catch these errors.
A recent study addressed the potential of AI in helping consultants generate research materials for a mock trial study: ‘The Efficacy of Social Influence Manipulation in an Eyewitness Experiment Conducted on an Online Platform’. One of the key components that this study attempted to replicate was social pressure from a lineup administrator. In the in-person version preceding this study, a confederate played the role of a lineup administrator, delivering ‘pressuring prompts’ like “Why don’t you take another look?” if the witness tried to reject the lineup. However, one concern that arose while running participants was that some of them believed that the ‘lineup administrator’ didn’t fit the image of an investigator that they had in their mind. In other words, mock jurors were distracted (and potentially influenced) by the appearance of the administrator. Therefore, simple audio and video recordings of a lab member to use in place of the in-person administrator could decrease believability and subsequent engagement. Moreover, it was difficult to experimentally control a person’s delivery regarding tone of voice so that the end result was perceived as neutral by most participants. Since this was not something that could reasonably replicate online in a short time frame, they found a way to ensure that crucial instructions could be delivered in an engaging format with the use of an AI-generated administrator: Detective Stetson.
Using Microsoft CoPilot to generate an image of a ‘serious, forensic lineup administrator’, the resulting character named ‘Detective Stetson’ was created:
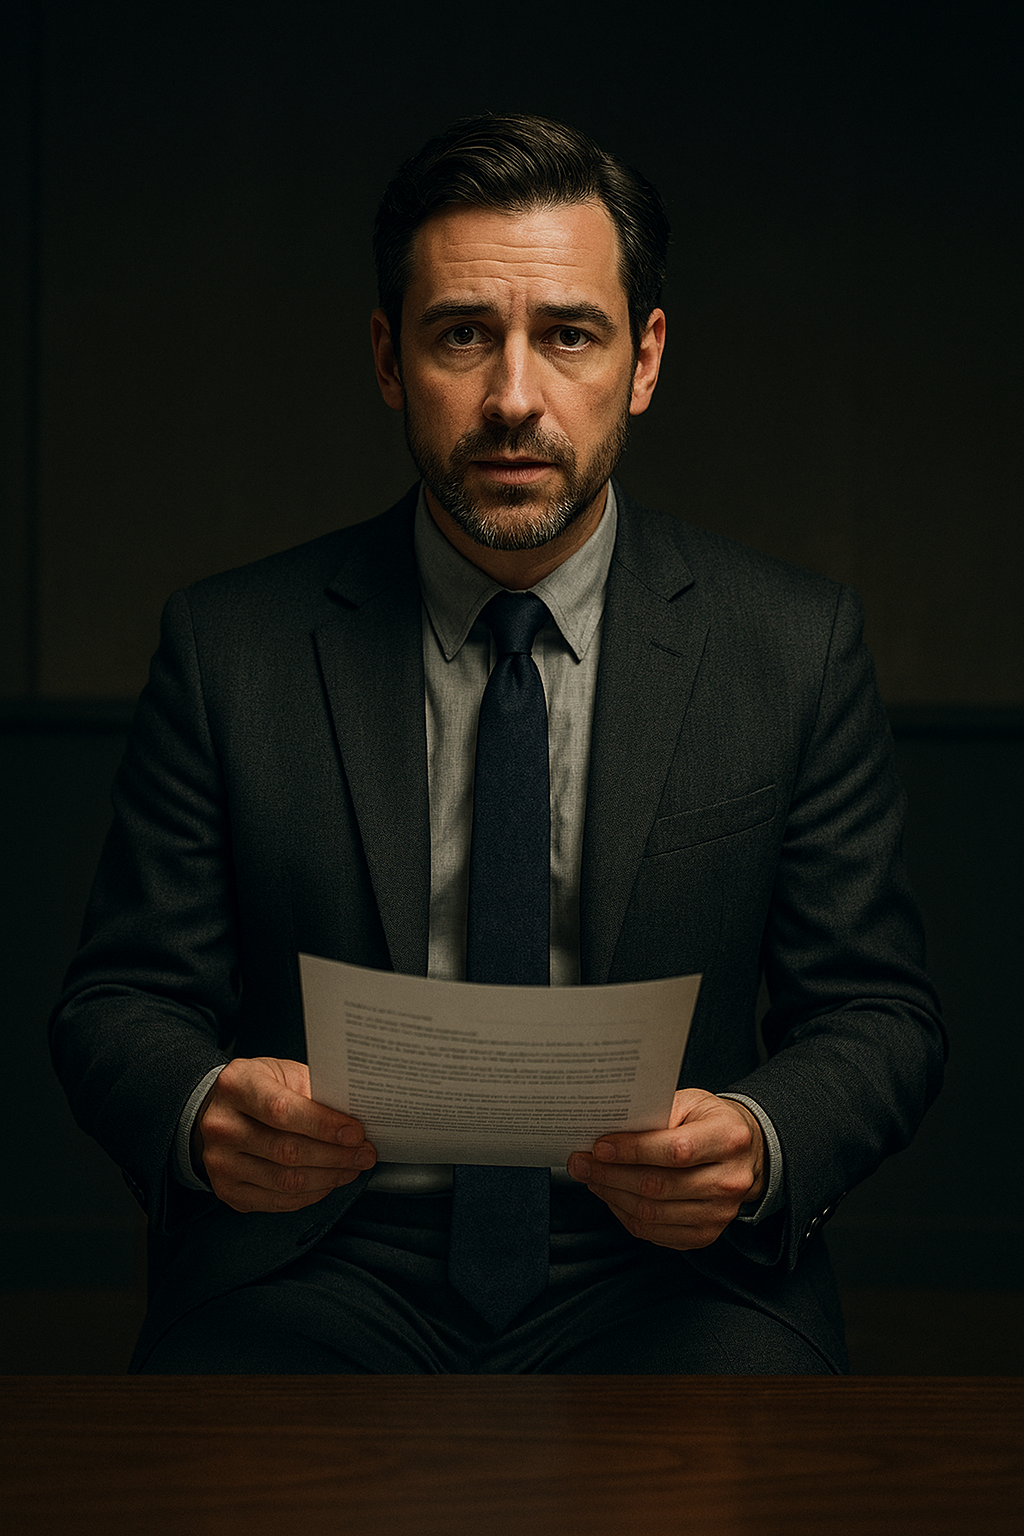
Then, using a publicly available AI video generator called HeyGen, the image was animated utilizing an audio prompt script, with instructions indicating that the voice should be ‘professional and neutral’. From this starting point, several audio and video clips were generated to serve as instructional material to embed in the online study.
It is important to note that while the overall trends in witness behavior remained the same, the perceived social pressure experienced by the participants was reported to be slightly lower than the pressure from an in-person administrator. Yet, this instruction format was well received by participants and allowed us to run the experiment with minimal participant removal due to lack of engagement, minimizing extraneous costs. In total, over 1,200 participants completed the online study within a few days while having a similar running cost as the in-person study (400 participants).
Issues with participant engagement are common problems trial consultants face in the field. While it can be very cost and time effective to run online sample studies, it can become difficult to ensure that the participant is actively participating (Han, 2022). So, AI integration does offer a unique opportunity to address this gap. While the inclusion of attention-check questions is beneficial for coding purposes and reducing chances of bot-participants slipping through the cracks, including auditory or video readings of instructions helps increase odds of getting the most useful data possible. Increasing attention and participant engagement helps to reduce overall confusion on tasks or questions in the study, thus cutting down on the number of data quality rejections.
Additionally, AI-tools offer a unique opportunity to increase consistency, if not neutrality, in the delivery of instructions. This could be beneficial for both online and in-person mock trials and pre-trial research to ensure that results are minimally confounded by outside factors from a third-party. The reduction of outside pressure is crucial when assessing participant’s attitudes, especially in circumstances as high stakes as legal proceedings. And while research on this matter needs to be expanded, the potential for AI-tools to offer greater neutrality in things like focus group administration could go a long way in increasing the accuracy of predictive data. It could even be used to test out what info is the most relevant in a testimony by showing participants different versions of AI-generated video highlighting different aspects of the case to gauge effectiveness.
Existing research on witness testimony in criminal cases indicates that positive outcomes accompany a confident witness who uses concrete wording. However, a prime example of this concept going wrong can be seen in the study ‘Calibration trumps confidence as a basis for witness credibility’ (Tenney et al., 2007). In this study, they varied the level of the mock-witness’s confidence to state that they were ‘completely confident’ or ‘not certain’. Then they introduced the fact that the witness in both conditions mistakenly said the crime took place at 7:00pm instead of 8:15pm. But when participants were asked to rate the witness’s credibility, the confident witness’s credibility had dropped to a score below even that of the uncertain witness. Though a fact like misremembering the timeframe of the crime can be minimized through proper witness prep, this highlights that there are likely many similar circumstances that can sway the jury in a way we can’t predict. What if a particularly emotional statement leads the jury to see the witness as too volatile to have made an impartial account of the criminal event? Or what if an emphasis on only the concrete aspects of a case with minimal appeals to pathos comes across as flat and unpersuasive to that particular jury pool? The opportunity for AI-generated material to help field all of these variations in advance so that each legal team can truly put their best foot forward is revolutionary.
There is huge potential for AI tools to be utilized in trial consulting, but it is important to weigh the potential benefits and harms with every use. There is no one-size-fits-all best tool to apply with a broad brush, and thus, consultant and firm discretion remains the most important prerequisite.
Citations:
Allen, J., & Hallene, A. (2026). How to avoid accidental disclosure when using AI [Review of How to avoid accidental disclosure when using AI]. Abaesq. https://www.americanbar.org/groups/senior_lawyers/resources/voice-of-experience/2026-may/client-confidentiality-and-ai-how-to-avoid-accidental-disclosure/
Han, S. (2022). Digital vs In-Person Qualitative Research: Choosing the Right Approach. In Sago. https://sago.com/en/resources/blog/digital-vs-in-person-qualitative-research/
Jaitley, A., Linna Jr, D. W., Rodriguez, X., Subrahmanian, V. S., & Tao, S. (2026). Artificial Intelligence in Federal Courts: A Random-Sample Survey of Judges | New York City Bar Association [Review of Artificial Intelligence in Federal Courts: A Random-Sample Survey of Judges | New York City Bar Association]. In New York City Bar Association. https://www.nycbar.org/reports/artificial-intelligence-in-federal-courts-a-random-sample-survey-of-judges/
Májovský, M., Černý, M., Kasal, M., Komarc, M., & Netuka, D. (2023). Artificial Intelligence Can Generate Fraudulent but Authentic-Looking Scientific Medical Articles: Pandora’s Box Has Been Opened (Preprint) [Review of Artificial Intelligence Can Generate Fraudulent but Authentic-Looking Scientific Medical Articles: Pandora’s Box Has Been Opened (Preprint)]. Journal of Medical Internet Research, 25. https://doi.org/10.2196/46924
Ellis, L., & Breitenstein, M. (2026). When ‘Smarter’ Still Means Harder: Lessons Learned from an AI Model’s Flawed Literature Review [Review of When ‘Smarter’ Still Means Harder: Lessons Learned from an AI Model’s Flawed Literature Review]. Thejuryexpert.Com. https://thejuryexpert.com/2026/04/when-smarter-still-means-harder-lessons-learned-from-an-ai-models-flawed-literature-review/
Tenney, E. R., MacCoun, R. J., Spellman, B. A., & Hastie, R. (2007). Calibration trumps confidence as a basis for witness credibility. Psychological Science, 18(1), 46–50. https://doi.org/10.1111/j.1467-9280.2007.01847.x